dbt 2.0 & Info Schema
dbt 2.0 changes what lands in target/. dbt docs generate no longer writes catalog.json, and dbt can now write a parquet information schema to target/info_schema/v1/ — a typed, versioned snapshot of your project that carries everything the JSON artifacts did, and on dbt Fusion quite a bit more.
dbdocs works with dbt 2.0 either way. This page explains the two paths and walks you through switching dbdocs onto the information schema.
Two ways to read a dbt 2.0 project
| Default (JSON artifacts) | Info schema (opt-in) | |
|---|---|---|
| Reads | manifest.json (+ catalog.json if present) | target/info_schema/v1/*.parquet, with any JSON artifacts as enrichment |
| Column types | Only what your YAML declares (no catalog on dbt 2.0) | Inferred by dbt for every column it can see |
| Column-level lineage | Parsed from compiled SQL by dbdocs | Computed by dbt itself (dbt Fusion with strict static analysis) |
| Extra install | none | pip install "dbdocs[info-schema]" (adds DuckDB) |
| Turned on by | nothing — it's the default | info_schema: true in dbdocs.yml |
You don't have to switch. With no catalog, the default path builds from the manifest alone and simply knows less about your columns. Switch when you want the fuller picture.
1. Install the extra
The info-schema reader uses DuckDB to read parquet. Without the extra, enabling the option stops with info_schema needs DuckDB: install it with pip install 'dbdocs[info-schema]' rather than failing somewhere obscure.
2. Have dbt write the info schema
Add --generate-info-schema to the dbt command you already run:
Strict static analysis is what makes dbt Fusion compute column types and column-level lineage for every model and store them in the info schema.
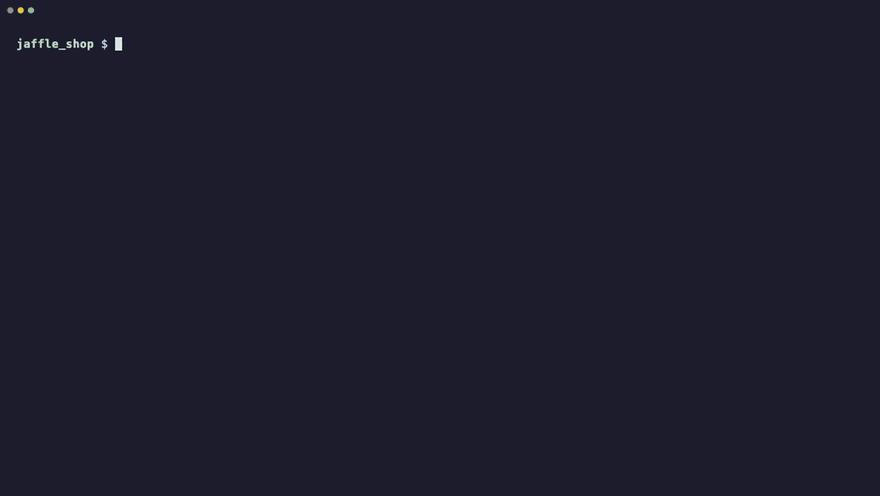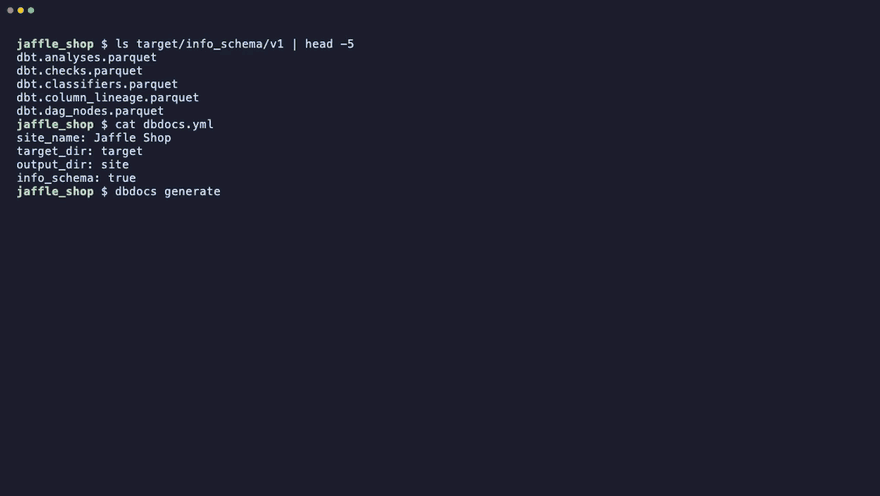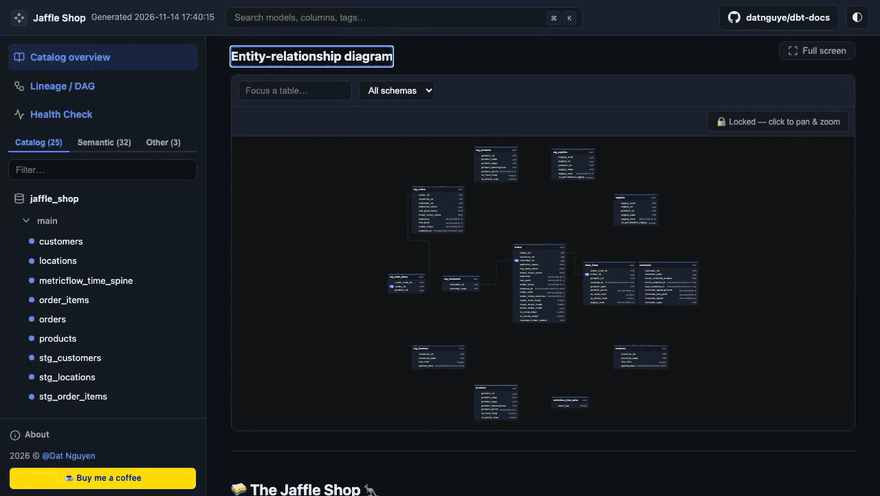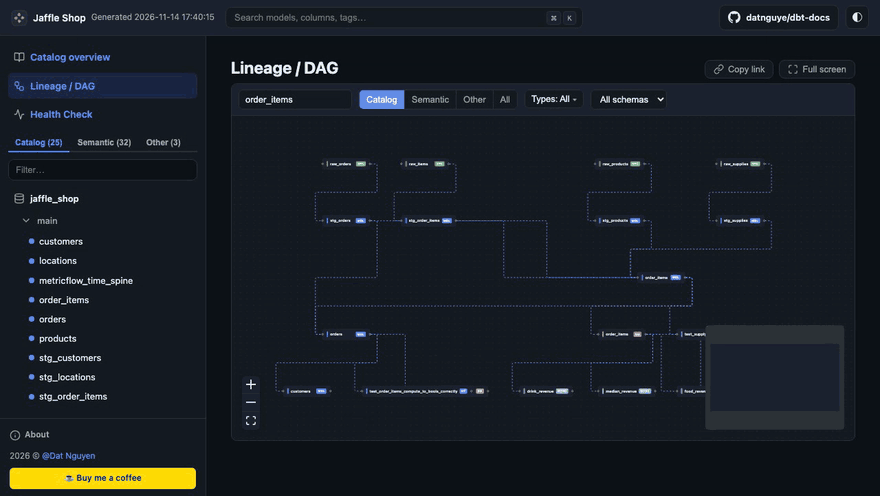
Either way you end up with target/info_schema/v1/ full of dbt.*.parquet files. dbt compile works too if you don't need test results on the Health page.
3. Turn it on in dbdocs.yml
# dbdocs.yml
target_dir: target
info_schema: true
# info_schema_dir: target/info_schema/v1   # only if dbt writes it elsewhere
That's the whole switch: every dbdocs generate and dbdocs deploy now reads the info schema. info_schema_dir defaults to <target_dir>/info_schema/v1; a relative path that climbs out of the project with .. is rejected, same as target_dir.
Trying it once, or turning it off for one run
The CLI flags override the config for a single run, so you can try the info schema before committing to it, or skip it once without editing the file:
dbdocs generate --info-schema                 # on for this run
dbdocs generate --no-info-schema              # off for this run
dbdocs generate --info-schema-dir path/to/v1  # a different directory
dbdocs deploy takes the same three flags. See the CLI Reference.
4. Generate as usual
Nothing else changes: same site, same ERD, same REST API. The site's metadata records artifact_source: info_schema, so you can tell which path built it.
How the two sources combine
The info schema is the base; any manifest.json, catalog.json or run_results.json left in target_dir only fills gaps:
- The parquet decides which models, sources, tests and semantic objects exist, and its values win. A JSON record only supplies fields the parquet left empty.
- Column types take the most trustworthy source available: the warehouse type from
catalog.json, then the type dbt measured, then the one declared in your YAML, then the one dbt inferred. - Column-level lineage comes from dbt when it computed some. dbdocs keeps only the columns that actually feed a value — join, filter and grouping keys that dbt records as merely read are left out, exactly as the SQL-parsed lineage leaves them out. When dbt computed none, the SQL-parsed lineage stays.
- Health uses the latest dbt run in the info schema that ran tests, so a later
dbt docs generatecan't wipe your test results the way it overwritesrun_results.json.
So it's safe to keep the JSON artifacts around — they can only add detail, never override what dbt wrote to the info schema.
Troubleshooting
| You see | Means | Fix |
|---|---|---|
info_schema directory not found: … | No parquet where dbdocs looked | Re-run dbt with --generate-info-schema, or point info_schema_dir at the right folder |
Unsupported info_schema schema_version … | dbt wrote a newer info-schema layout than this dbdocs knows | Upgrade dbdocs |
info_schema needs DuckDB … | The extra isn't installed | pip install "dbdocs[info-schema]" |
Ignoring … as info_schema enrichment: … (warning) | A JSON artifact in target_dir is unreadable or corrupt | Harmless — it's skipped. Delete it or re-run dbt to quiet the warning |
| Health page missing | No dbt run that executed tests is recorded | Run dbt build or dbt test with --generate-info-schema |
| Thin column lineage | dbt computed none (dbt Core, or Fusion without strict analysis) | Use dbt Fusion with --static-analysis strict |
An explicit opt-in never falls back to the JSON path silently: if the info schema is missing or unreadable, dbdocs stops and tells you, rather than quietly building a different site than the one you asked for.